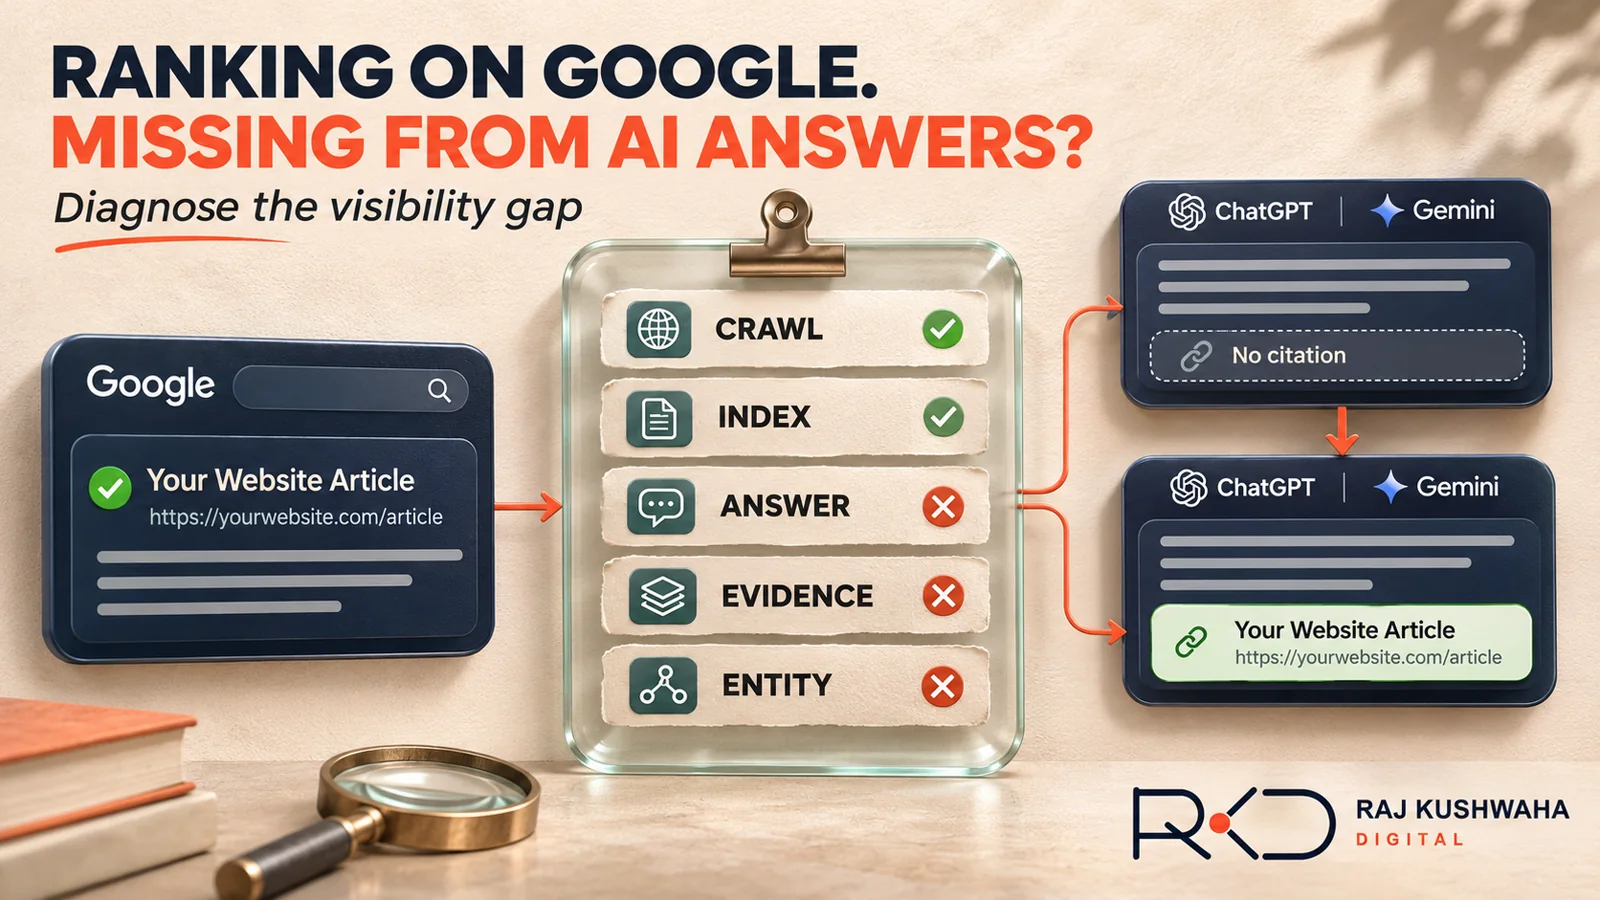
1. Why Google ranking and AI citation are different signals
Traditional search ranks pages for a query. An AI answer can first interpret the question, retrieve passages from one or more indexes, compare sources and decide which evidence to cite. A page can perform well in Google and still miss a different system's crawl, index or retrieval stage.
This is why there is no single 'AI ranking' switch. The useful question is where the evidence chain breaks: access, index, answer, evidence or entity.
| Signal | What to check | Common failure |
|---|---|---|
| Access | Robots rules, CDN and server response | The crawler is allowed in robots.txt but blocked elsewhere |
| Index | Canonical, noindex, snippets and page quality | The wrong URL is indexed or the page is ineligible |
| Answer | A direct response to one clear question | The useful answer is buried under generic copy |
| Evidence | Primary sources, dates, methods and original detail | Claims are easy to repeat but hard to verify |
| Entity | Author, organisation, service and location consistency | The system cannot confidently connect the page to the business |
2. Start with access and index eligibility
OpenAI documents OAI-SearchBot as the crawler used for ChatGPT search. GPTBot is used for potential model training and can be controlled independently. Allowing OAI-SearchBot removes one possible access barrier; it does not create a citation.
Google says its AI experiences use the same foundational SEO requirements as Search. Important pages should return a successful response, be indexable, use the intended canonical URL and permit previews that can support a result. Robots rules, firewalls and CDN bot controls must agree.
- Fetch the exact canonical URL as a normal browser and as the relevant crawler where your tools allow it.
- Check robots.txt, noindex, canonical tags, snippet controls and redirect chains together.
- Keep the XML sitemap current and link important pages from crawlable navigation or related content.
- Do not add llms.txt, special AI schema or artificial content chunks as a substitute for indexable, useful pages.
3. Give answer systems evidence worth retrieving
A useful page answers one real question near the top, then supports the answer with process detail, dates and primary sources. Case-study numbers should explain the measurement period and source. Advice should state when it applies and where it may not.
Generic claims such as 'we drive transformative growth' are easy to replace. A documented method, a dated observation, a useful comparison or firsthand experience gives a retrieval system something specific to represent.
- Lead with a concise answer, not a long introduction.
- Use descriptive headings that match follow-up questions.
- Link changing claims to the original platform documentation.
- Show authorship, review dates and the method behind business evidence.
4. Make the business entity easy to verify
Organisation, author, service, article and breadcrumb data should use stable names, identifiers and canonical URLs. The visible byline should link to a real author profile. The address, phone, service descriptions and social profiles should remain consistent across the website and credible business listings.
Structured data can reduce ambiguity, but it should describe visible content rather than become a hidden layer of promotional claims. Valid markup does not guarantee a citation or special result.
5. Measure the gap instead of guessing
Google Search Console's generative AI performance report can separate clicks and impressions from supported AI experiences. Bing's AI Performance area can show citations and grounding queries, while its Topics Portfolio beta groups visibility into topic clusters and opportunity queries.
Bing describes Topics Portfolio data as directional and approximate, and topic classification can be imperfect. Use it to find investigation areas, not as proof that one edit caused an appearance. In analytics, separate referrals from AI platforms and judge landing-page engagement and qualified actions, not traffic alone.
6. A practical 30-minute visibility audit
Choose one commercially important question and audit the single page that should answer it. This keeps the diagnosis focused and prevents broad content rewrites without evidence.
- Confirm the page returns HTTP 200, is canonical, indexable and present in the sitemap.
- Check Google, Bing and OAI-SearchBot access at robots, CDN and server level.
- Read the first screen and confirm it gives a useful answer without requiring context from another page.
- Add primary sources, a review date and firsthand proof where the page makes material claims.
- Connect the page to the relevant service, author profile, proof page and next action.
- Record the baseline, request recrawling where appropriate and review platform-specific data after enough time has passed.
7. RKD view: fix the evidence chain, not just the copy
If a site already ranks, publishing ten more generic AI SEO articles is rarely the first move. Diagnose the missing stage, strengthen the page that should win and make the supporting evidence easy to verify. The goal is not to manipulate an answer engine. It is to become a reliable source when the system needs an answer your business can genuinely support.
Check the platform guidance
Sources reviewed 04 November 2026. These links support the platform-specific statements above; they do not imply a partnership or endorsement.
- OpenAI: overview of OpenAI crawlersOfficial distinction between OAI-SearchBot, GPTBot and ChatGPT-User.↗
- Google Search Central: AI optimization guideOfficial guidance on technical eligibility, unique content, page experience, structured data and measurement for Google's AI experiences.↗
- Google Search Console: Generative AI performance reportOfficial report scope, metrics and known limitations for supported Google AI experiences.↗
- Bing Webmaster Blog: Topics Portfolio betaMicrosoft's announcement, topic metrics, opportunity queries and beta limitations.↗